HappyHorse 1.0.
Cinema. In Every Language.
Alibaba's flagship video model. Built to challenge Seedance 2.0.
1080p with native audio, 7-language lip-sync, multi-shot up to 15s. From $0.2002 per second.
HappyHorse 1.0 is a video generation model from Alibaba that turns a text prompt or a first-frame image into 1080p clips of 3 to 15 seconds, with dialogue, ambient sound and lip-sync in seven languages generated in the same pass. On Segmind it runs through one API key at $0.2002 per second at 720p and $0.3432 per second at 1080p, audio included.
What Makes It Cinematic
Cinematic. Multilingual.
#1 on three of four arena tracks.
Cinema-grade output,
Alibaba's answer to Seedance 2.0.
15-billion-parameter unified Transformer. Beats Seedance 2.0 on three of four Artificial Analysis Video Arena tracks, while undercutting it on per-second pricing.
Voice. Ambient. Foley.
One forward pass.
Veo 3.1 and Kling 3.0 Pro charge 50 to 100% more per second to add audio. HappyHorse generates video and synced audio in one Transformer pass, at no extra cost.
Phoneme-level. Out of the box.
Lowest reported word-error rate of any production video model, at ~14.6% across all seven supported languages.
From $0.2002/sec
Run 100 variants for the cost of one studio reshoot. No subscriptions, no minimums.
One prompt.
Multiple cuts. Native 1080p.
Up to 15 seconds with character continuity across shot changes. The model decides coverage automatically.
How It Works
Brief to cinematic spot.
For pocket change per second.
Direct & Reference
Prompt + up to 9 references.
Start from a text prompt, an image, or a multi-asset brief: faces, environments, palettes, voice samples. One unified endpoint, /v1/happyhorse, accepts every combination of inputs.
Reference images lock identity and style. Voice references guide the dialogue. The model figures out the role of each asset.
9 images · 3 videos · voice sample
Generate Sound + Vision
One forward pass. ~80 to 160 seconds on Segmind.
A unified single-stream Transformer denoises text, image, video, and audio tokens together. Eight DMD-2 steps, classifier-free guidance disabled.
1080p, 24 fps, multi-shot, dialogue and Foley aligned to the frame. No separate audio model, no post-production stitch.
Edit, Localize, Iterate
20+ variants for the cost of one studio shot.
Pass a source video plus reference images to swap a product, wardrobe, or background while preserving motion and timing. Re-lipsync existing footage to any of 7 languages without reshooting.
At $0.3432 per second, you can run a dozen creative variants for a single ad spot's traditional production budget.
Use Cases
Built for commerce.
Cinematic by default.
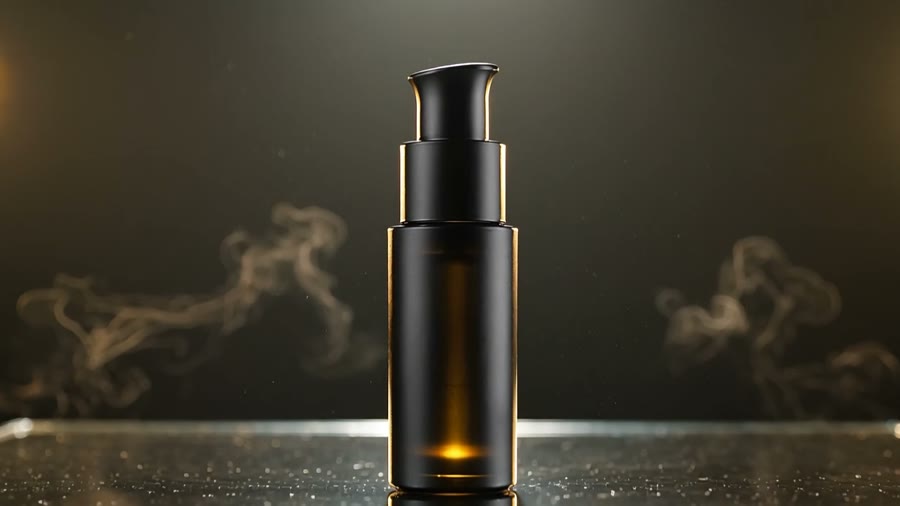
Product video at catalogue scale
Image-to-video PDP showcases with push-ins, soft light sweeps, matched Foley. Batch-generate 20 variants from a single hero shot.
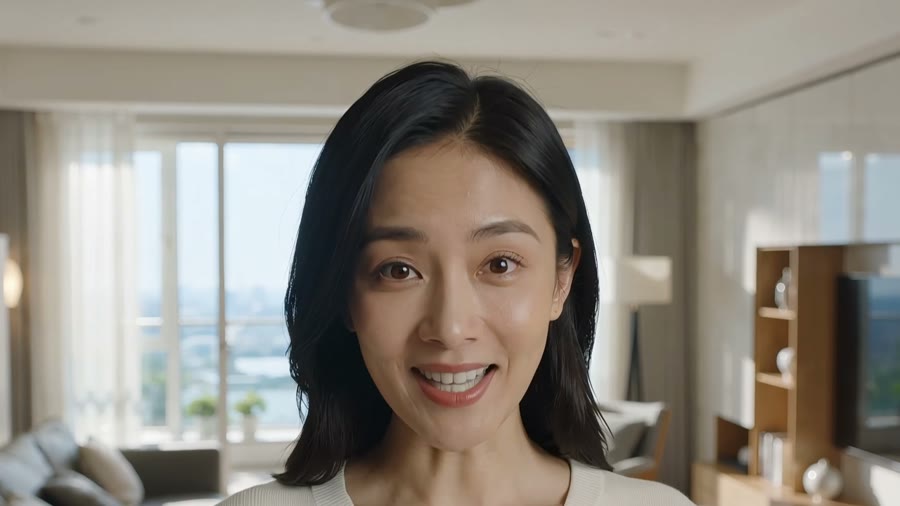
One creative. Seven languages.
Native phoneme-level lip-sync in Mandarin, Cantonese, English, Japanese, Korean, German, and French. No dub-and-relipsync passes.
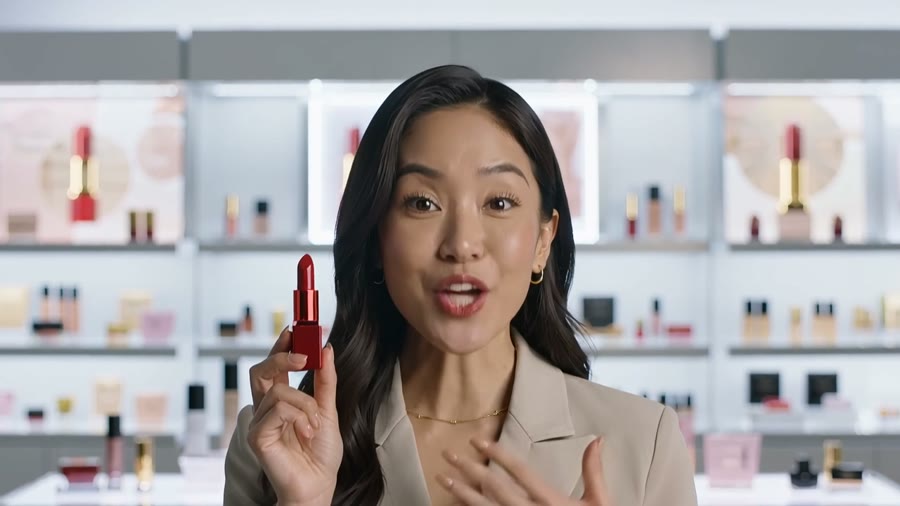
Persistent live-commerce presenters
Subject-to-video with up to 9 reference images. Identity preserved across cuts and languages, perfect for branded virtual hosts and mascots.
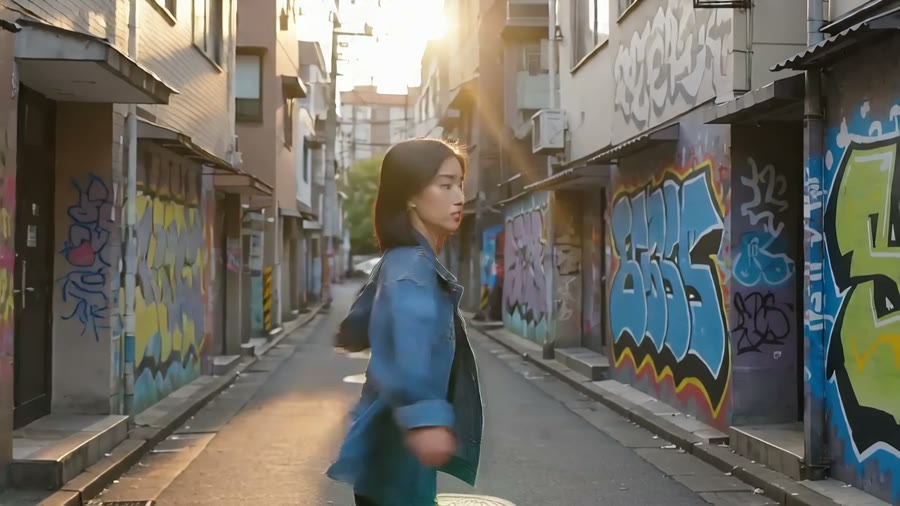
Vertical video with native audio
9:16 generations for TikTok, Reels, Shorts, Douyin, and Xiaohongshu. Dialogue and ambient sound in the same pass, no separate dubbing pipeline.
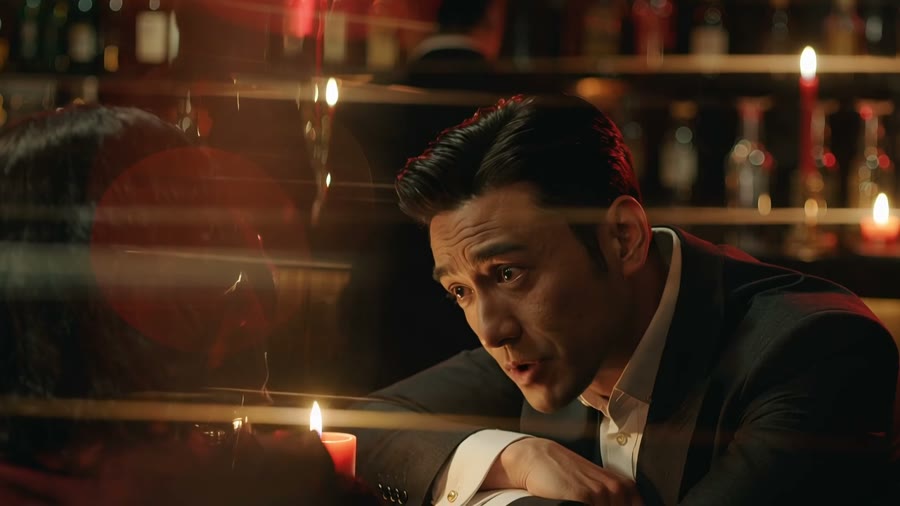
Cinematic spots, dialogue and all
Multi-shot brand films with dialogue, ambient sound, and Foley produced together. Production quality formerly locked behind closed APIs.
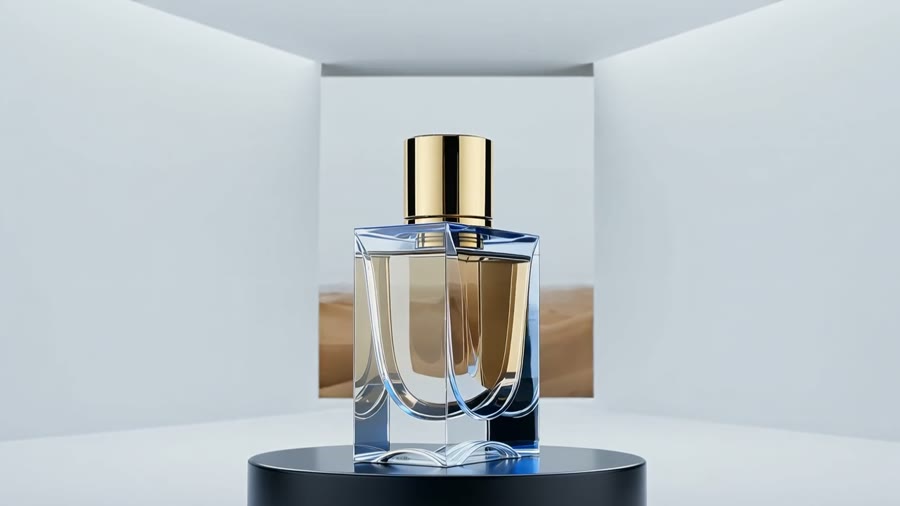
Swap product, wardrobe, or background
Video-to-video and subject-and-video-to-video edits change on-screen elements while preserving camera moves, motion, and timing. No reshoot.
Under the Hood
Built different.
Architecturally speaking.
Unified Token Sequence
Text, image, video, and audio tokens are jointly denoised in one Transformer. No separate audio model, no cross-attention. The model learns alignment, not stitching.
DMD-2 Distillation
Distribution Matching Distillation v2 cuts inference to 8 denoising steps and runs without classifier-free guidance. Far below the 25 to 50 steps typical for diffusion video.
Per-Head Modality Gates
Learned scalar gates dampen destructive cross-modal gradients during joint training, keeping the audio and video branches from competing for capacity. Reported in technical notes, not yet peer-reviewed.
Technical Specifications
Head to Head
The model that beats Seedance 2.0.
Alibaba's flagship leads three of four Artificial Analysis Video Arena tracks against the current state of the art, with audio always included and 7-language lip-sync built in.
3 of 4
tracks at #1 on the Artificial Analysis Video Arena
$0.3432/sec
at 1080p with synced audio. Veo 3.1 and Kling 3.0 Pro charge 50 to 100% extra to add it.
~80 to 160s
end-to-end for a 5-second clip on the Segmind API, 720p to 1080p
Track
HappyHorse 1.0Alibaba
Seedance 2.0ByteDance · current SOTA
Kling 3.0 ProKuaishou
Artificial Analysis Video Arena, blind preference Elo, late-April 2026 snapshot. Arena prompts skew toward portrait and dialogue content; long-action and reference-edit categories remain competitive across models. All per-second pricing reflects current Segmind list pricing for the named models with audio enabled where applicable. Seedance 2.0 uses token-based pricing; the listed per-second figure is a typical 5-second 1080p call ($1.21 average).
Key facts
- Developer
- Alibaba (Taotian Future Life Lab)
- Architecture
- 15-billion-parameter unified Transformer that generates video and audio in one pass
- Resolution
- 720p or 1080p
- Clip length
- 3 to 15 seconds per generation, with multiple shots in one clip
- Aspect ratios
- 16:9, 9:16, 1:1, 4:3 and 3:4 for text-to-video
- Inputs
- Text prompt, optional first and last frame, optional speech audio (MP3 or WAV, 3 to 30 seconds)
- Audio
- Dialogue, ambient sound and effects generated with the video
- Lip-sync languages
- English, Mandarin, Cantonese, Japanese, Korean, German and French
- Price on Segmind
- $0.2002 per second at 720p, $0.3432 per second at 1080p, audio included (as of 13 Oct 2026)
- Typical wait
- About 164 seconds per generation, 30-day average on Segmind (as of 13 Oct 2026)
Flexible plans for everyone
Whether you're just starting out or need enterprise-grade power, we have a plan that fits your needs.
Business
For working with production environments and professional use cases.
- $99 monthly credits
- 100 GB Storage
- 500 RPM
- 2 business day support
- Pixelflow Premium Templates
Scale
For large companies that requires custom solutions and private deployments.
- $599 monthly credits
- 1 TB Storage
- 1000 RPM pooled
- 1 business day support
- Detailed usage analytics
Enterprise
Custom solutions with enterprise-grade security and support
Frequently asked questions
What is HappyHorse 1.0?
HappyHorse 1.0 is Alibaba's video generation model. It creates 720p or 1080p clips of 3 to 15 seconds from a text prompt or a first-frame image, and generates dialogue, ambient sound and lip-synced speech in the same pass. On Segmind it runs through a pay-as-you-go API with no GPUs to manage.
How much does HappyHorse 1.0 cost on Segmind?
HappyHorse 1.0 costs $0.2002 per second at 720p and $0.3432 per second at 1080p on Segmind, with audio included at no extra charge. A 5-second clip costs about $1.00 at 720p and $1.72 at 1080p. There is no subscription or minimum spend: you pay per generation.
Which languages does HappyHorse 1.0 lip-sync?
HappyHorse 1.0 lip-syncs speech in seven languages: English, Mandarin, Cantonese, Japanese, Korean, German and French, aligning mouth movement at the phoneme level. You can also drive a clip with your own speech recording, an MP3 or WAV file of 3 to 30 seconds, through the audio_url input.
How long can a HappyHorse 1.0 video be?
A HappyHorse 1.0 clip runs 3 to 15 seconds per generation, and one clip can contain several shots. Iterate with 3 to 5 second clips at 720p, then render the final cut at 1080p. For longer stories, generate several clips and edit them together.
How does HappyHorse 1.0 compare with Seedance 2.0 and Kling 3.0 Pro?
HappyHorse 1.0 includes audio in its price: $0.3432 per second at 1080p on Segmind, close to Kling 3.0 Pro with audio at $0.336 per second, while Seedance 2.0 is billed per token. At launch in April 2026, HappyHorse 1.0 ranked first for text-to-video and image-to-video on the Artificial Analysis Video Arena.
How long does HappyHorse 1.0 take to generate a video?
HappyHorse 1.0 takes about 164 seconds per generation on Segmind, the 30-day average as of 13 October 2026. 720p renders finish faster than 1080p, so iterate on a prompt at 720p and switch to 1080p for the final render.
What is the difference between HappyHorse 1.0 and HappyHorse 1.1?
HappyHorse 1.1 is the successor to HappyHorse 1.0 from the same Alibaba lab. It adds reference-to-video with up to nine reference images and costs $0.2574 per second at 1080p, against $0.3432 for HappyHorse 1.0. HappyHorse 1.0 still accepts your own speech audio for lip-sync, which HappyHorse 1.1 does not.
How do I use HappyHorse 1.0 on Segmind?
Try HappyHorse 1.0 in the browser on its Segmind model page, or create an API key and send a POST request to https://api.segmind.cyou/v1/happyhorse with a prompt and the x-api-key header. HappyHorse 1.0 returns the finished MP4 in the response. Add an image for image-to-video or an audio_url for lip-sync.
Cinema-grade output.
Cents per second.
Generate sound and sight together. Text, image, reference, and edit inputs in one endpoint. Roughly 80 to 160 seconds per clip on the Segmind API.
Last updated